


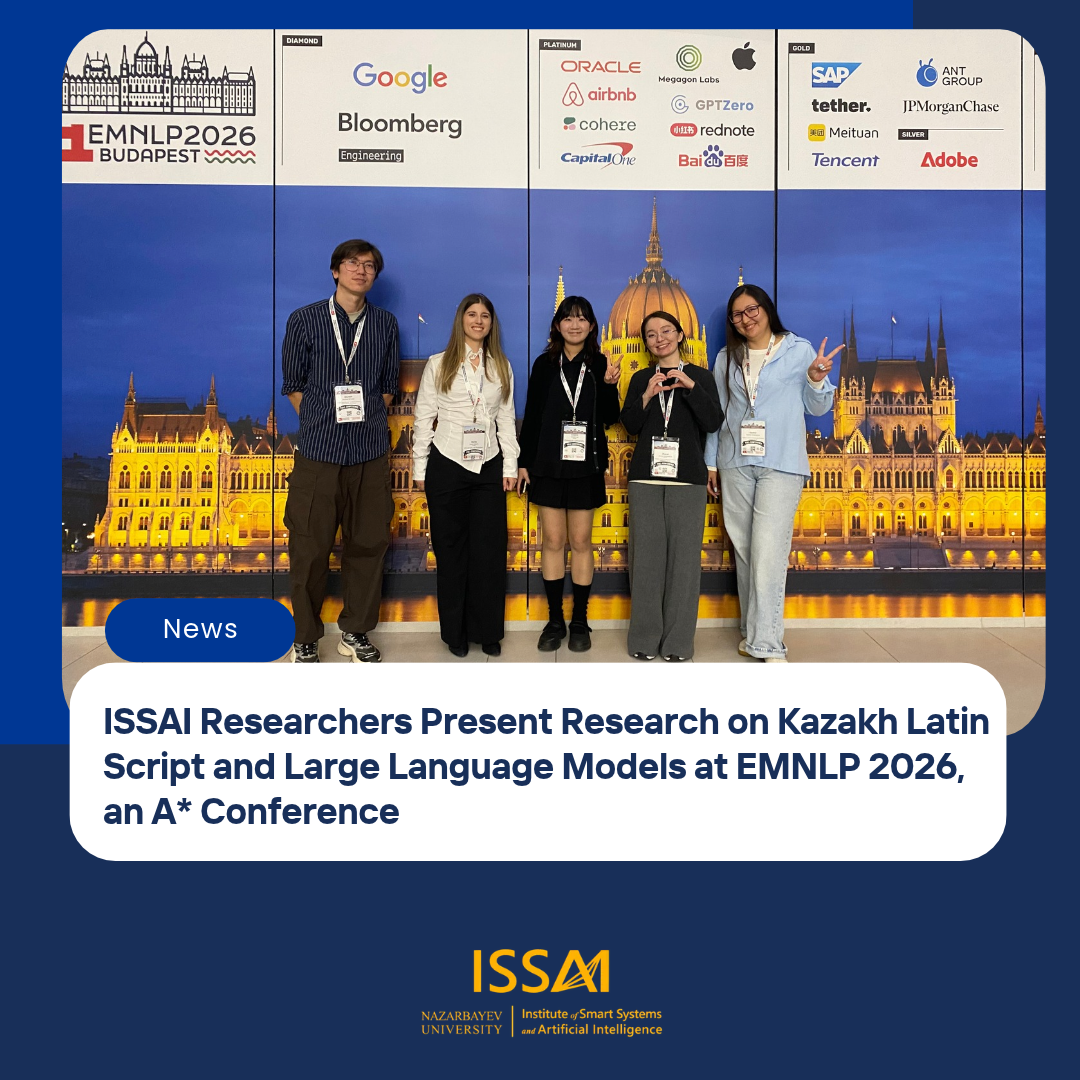
On October 27, 2026, researchers Akylbek Maxutov and Dr. Zhanat Makhataeva at the Institute of Smart Systems and Artificial Intelligence (ISSAI) at Nazarbayev University presented their research at the 2026 Conference on Empirical Methods in Natural Language Processing (EMNLP 2026), held in Budapest, Hungary, from October 24 to 29.
The paper, “Do LLMs Cross Alphabets? A Cross-Script Audit of LLMs Across Four Kazakh Latin Proposals”, was co-authored by Galammadin Askar, Arailym Mukhametkali, Nūrali Medeu and Prof. Huseyin Atakan Varol, Founding Director of ISSAI and Dean of the School of Computing and Artificial Intelligence (SCAI) at Nazarbayev University.
The study investigates how effectively large language models (LLMs) process Kazakh written in Latin script, addressing an important challenge as Kazakhstan explores the transition of the Kazakh language from Cyrillic to Latin script.
The researchers evaluated 13 language models across three benchmarks — KazMMLU, KazCulture, and GSM8k-Kazakh — adapted to four proposed Latin-script variants of Kazakh. By comparing model performance across writing systems, the study examined how script variation affects the accuracy and reliability of AI systems working with the Kazakh language.
The results revealed an average accuracy decline of 16.8 percentage points when models processed Kazakh in Latin script rather than Cyrillic. The findings also showed that differences in tokenization alone do not fully explain this performance gap. While prompt-based techniques offered limited improvements, LoRA fine-tuning recovered up to 20 percentage points for sufficiently large, reasoning-capable models.
The findings highlight the importance of ensuring that language models can reliably understand Kazakh across writing systems. The authors emphasize that incorporating Latin-script Kazakh data during pretraining or large-scale continued pretraining is essential to improving model performance, rather than relying solely on prompt-based adjustments.
The research was conducted as part of the KazNU project “Creation of a Large Language Model (LLM) to Support the Implementation of the Kazakh Language and Advance Technological Progress” (IRN of the program: BR24993001).
Through research on Kazakh language technologies and multilingual AI, ISSAI contributes to the development of artificial intelligence systems that better reflect Kazakhstan’s linguistic needs. Presenting this work at EMNLP 2026 provides an opportunity to share research on Kazakh language processing with the international natural language processing community and contribute to the development of more inclusive and linguistically capable AI systems.